
Applied AI studio · London & New York
Models are easy. Systems are hard.
Nightjar designs, builds and runs the agents, retrieval pipelines and evaluation harnesses that turn a promising model into software your operations can depend on.
Start a project
See the work
41
Systems in production
3.2M
Agent runs every week
claims-triage v14 · in production
eval 97.2% pass · 0 drift
In production at
Eight industries · nine countries
KINROSS FREIGHT
Halden Mutual
verity health
OAKHURST
Lumière Hotels
PALLAS BIO
Stratford Energy
northwind/os
(01) The gap
Most AI projects die somewhere between the demo and the deadline. We work in that gap: instrumented, evaluated and owned end to end.
Who
34 engineers, designers and evaluators who have shipped search, ranking and risk systems to millions of people.
How
Small senior teams, weekly releases, and an evaluation suite that stays with you after we leave.
(02) Capabilities
Five things we build, properly.
Every engagement ships to production with monitoring, guardrails and a scored test set. No slideware, no orphaned prototypes.
01
Agentic workflows
Multi-step agents that read, decide and act inside your stack, with human checkpoints exactly where the risk lives.
Tool use · Planning · Approvals
02
Retrieval & knowledge
Search that cites its sources across contracts, tickets and wikis. Permission-aware and sub-second.
Hybrid search · Reranking · ACLs
03
Evaluation harnesses
Golden sets, regression gates and live scoring, so every model change is a measured decision.
Evals · Red-teaming
04
Voice & documents
Phone agents and document vision that hold up against real-world noise, accents and bad scans.
Speech · OCR · Multimodal
05
Fine-tuning
Smaller models trained on your data, owned by you and deployed wherever you need them.
Distillation · On-prem
(03) Inside a system
What you own when we hand over.
Every system ships with the agent your team talks to and the evaluation suite that keeps it honest. Both stay with you.
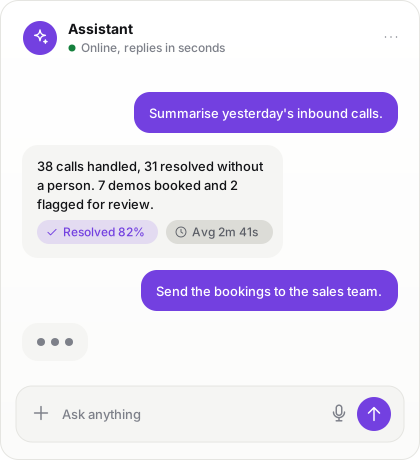
The agent, in your tools
It answers inside Slack and the CRM, cites its sources and hands off to a person when its confidence drops.
The eval suite that stays
Every release is scored against your own graded cases before it ships. You see the numbers, not a slide.
claims-triage v14
97.2%
pass-rate on 2,300 graded cases
0
regressions
1.4 s
p95 latency
£0.004
per answer
(04) How we build
First call to first production run in ten weeks.
01
Weeks 1–2
Discover
We map the workflow, pull real samples and agree what “good” means as a scored evaluation set, before anyone writes a prompt.
02
Weeks 3–5
Prototype
A working slice against your real data, scored against the eval set every day. You see the numbers, not a slide deck.
03
Weeks 6–9
Harden
Guardrails, fallbacks, observability, red-teaming and cost controls: the unglamorous work that makes it safe to switch on.
04
Week 10 →
Operate
We run it alongside your team: drift alerts, weekly eval reports and model upgrades shipped as measured releases.
(05) Selected work
Shipped, measured, still running.
Kinross Freight
Logistics
Exception agent resolves 71% of delayed-shipment emails without a human in the loop.
2026
Halden Mutual
Insurance
Claims triage over 40 years of policy wording. First response in 40 seconds, down from 9 minutes.
2026
Verity Health
Healthcare
Clinical-note summaries, evaluated against 2,300 physician-graded cases before go-live.
2025
Oakhurst Retail
Retail
A voice ordering agent handling 18,000 calls a week across 212 stores.
2025
Pallas Biotech
Life sciences
A distilled 8B model reads assay reports at one fourteenth of the cost of the API it replaced.
2024
(06) By the numbers
41
systems running in production today
97%
average evaluation pass-rate at launch
11
weeks, median from kickoff to production
0
prototypes left to gather dust in a drawer
(07) Start here
Have a workflow that should run itself?
Tell us where the work piles up. In thirty minutes we will tell you honestly whether AI is the answer, and what it would take to ship it.
Book a scoping call
hello@example.com